

Cinematic B-roll · 30-second 1080P footage from one prompt

Give wan3.0-video one scene idea and get a 30-second, 1080P, 16:9 cinematic B-roll shot with native camera movement, lighting, and audio.

Disclaimer: The content shown on this page is all generated by AI models and is for reference only; it does not constitute any guarantee of results. Actual output and Credits consumption are subject to "Usage Details" in the console.
Promos and launch openers need high-quality B-roll, but aerial and live-action shoots are not always available. Give wan3.0-video one scene idea and it generates a 30-second, 1080P cinematic long take in one pass: camera movement, shifting light, music, and ambient sound all come from the model, with no post-production editing or compositing. This walkthrough uses an "immortal mountain sea of clouds" scene; the same method works for landscapes, city skylines, seasonal textures, and brand mood openers. Call chain: qwen3.8-flash (optional, expands the scene idea into a cinematic prompt) → wan3.0-video (text-only input, one 30-second / 1080P / 16:9 video with native audio).

Actual output

This run generated a 30-second video in one pass: the camera glides over the sea of clouds from high altitude, approaches the immortal palace on the summit, looks down on the terrace, then pulls back and rises, ending on the pavilion fading into the peaks against the rising sun. The video is the complete output of one call with no post-processing. It is 1920×1080 / 30fps with synchronized stereo music and ambient sound, no silent segments, no dialogue or voiceover. The embedded video is a 540p compressed preview for faster loading; the generation setting is 1080P. Four keyframes map the beats: at about 1 second, a high-altitude view of the peaks and cranes; at about 11 seconds, the camera pushes in toward the palace; at about 24 seconds, it pulls back over the summit terrace and banquet; at about 28 seconds, the shot settles on the distant sea of clouds and rising sun.
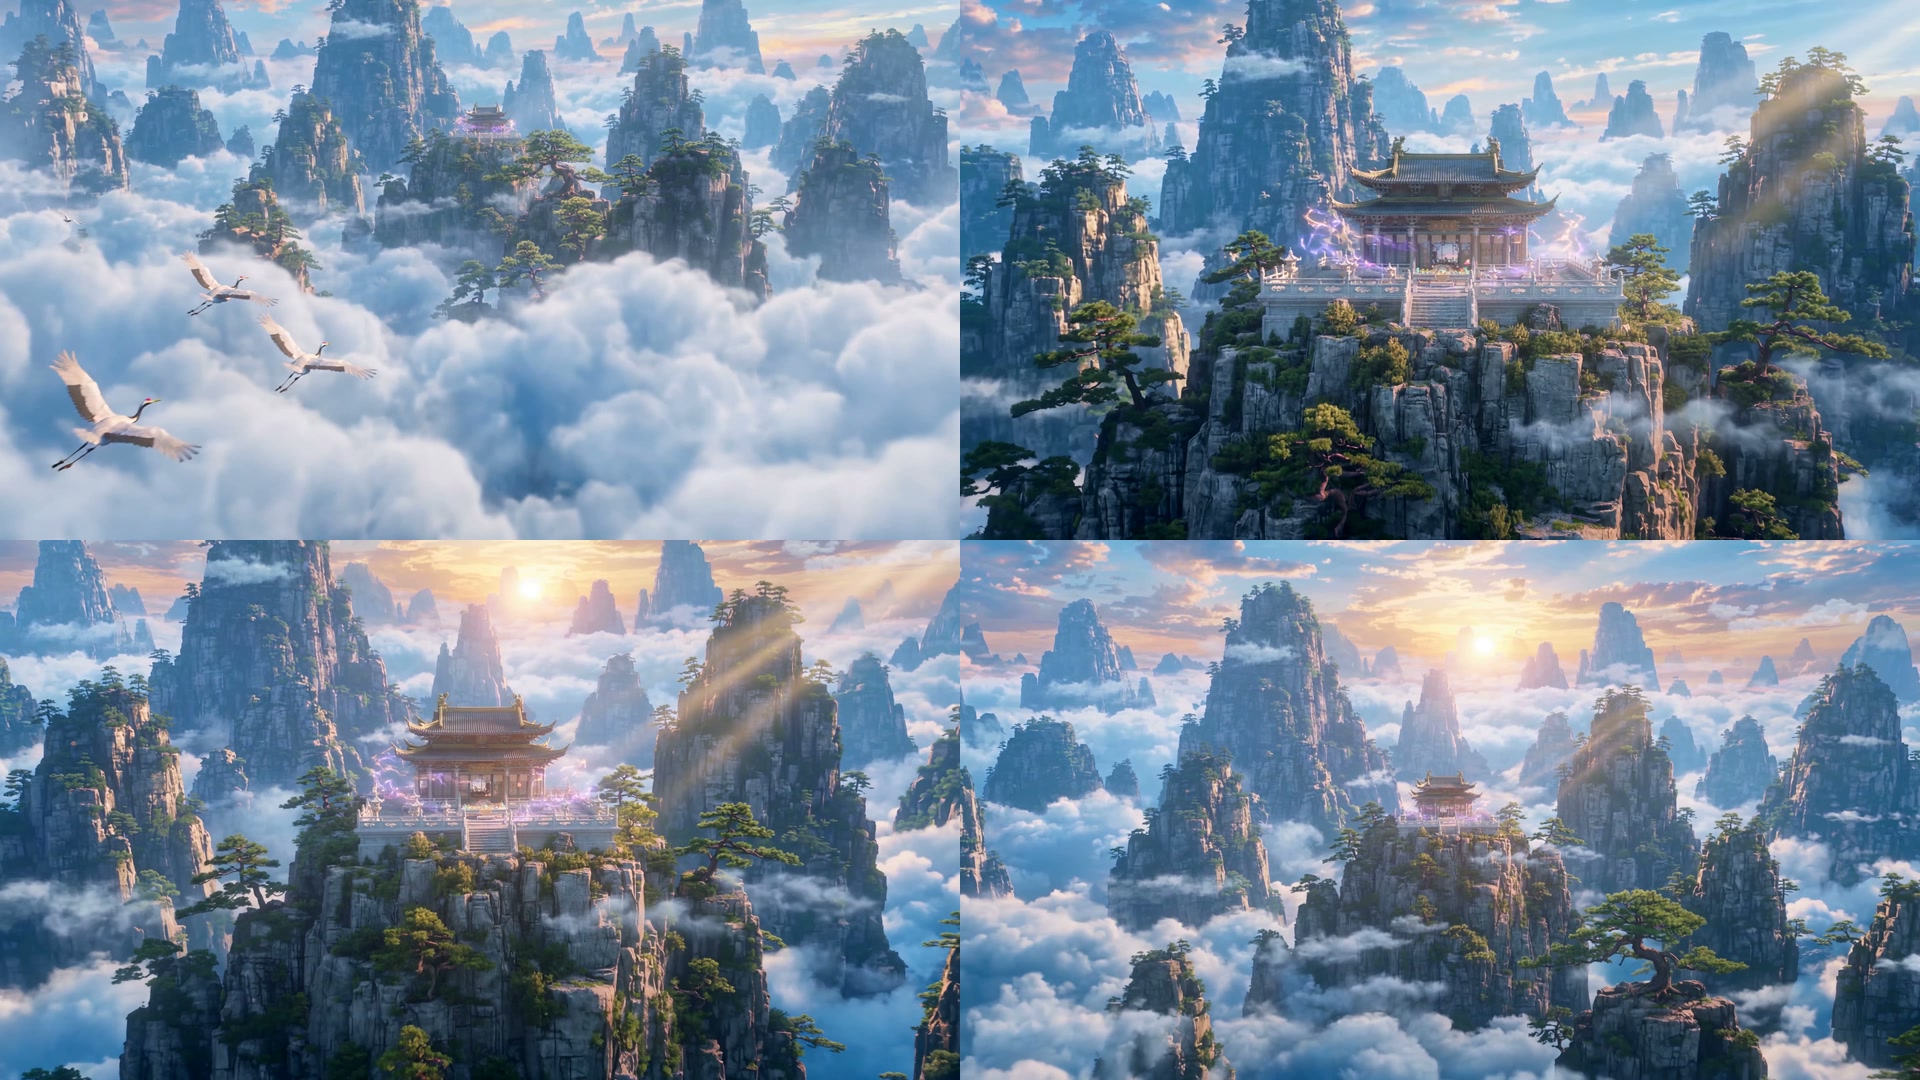
Four keyframes: high-altitude view, palace approach, pull-back overview, final wide shot
Measured settings for this run:
ItemValue
Model and modewan3.0-video · text-to-video (text-only input, no first frame or reference material)
Generation settingsduration 30 · resolution 1080P · ratio 16:9 · --watermark false
Output spec1920×1080 / 30fps / 30.0 seconds, H.264 video + AAC stereo
OutputOne 30-second video with native music and ambient sound

Steps: from one scene idea to a 30-second video

Two common settings: add --watermark false to every video command to turn off the model's bottom-right "AI generated" watermark; the CLI does not add a separate overlay. A 30-second 1080P video takes about ten minutes to generate, so use --async to get a task_id and poll manually instead of letting the client time out. Set the Token Plan Base URL and API key first. Token Plan keys start with sk-sp- and pair with the Token Plan Base URL:
export BASE_URL="https://token-plan.cn-beijing.maas.aliyuncs.com"
export API_KEY="sk-sp-xxxxxxxxxxxxxxxxxxxxxxxxxxxxxxxx"

① (Optional) Expand the scene idea into a cinematic prompt

# Follow the order: scene and lighting -> subject and action -> camera movement -> closing frame -> style and texture -> negative constraints. Output one continuous paragraph ready for text-to-video.
# Replace the theme in the message with your own subject (landscape aerial, city skyline, seasonal texture, brand mood opener); keep the structure.
bl text chat --api-key "$API_KEY" --base-url "$BASE_URL" --model qwen3.8-flash --message \
  "I am using the text-to-video model wan3.0-video to generate a 30-second, 1080P, 16:9 Chinese-style xianxia cinematic short. The theme is 'a banquet above the sea of clouds, an immortal mountain in a painting': on a sea of clouds, an immortal palace is holding a banquet, and the camera finally pulls back and rises, ending on the pavilion fading into the peaks against the rising sun. Expand it into one prompt ready for a text-to-video model: follow the order scene and lighting -> subject and action -> camera movement (push in / pass through clouds / pull back and rise) -> closing frame -> style and texture keywords -> negative constraints (no dialogue, no subtitles, no character close-ups), write one continuous paragraph without bullet points, 150-250 words."
Example expansion from this run (use it as reference for step ②; replace the subject and style words as needed):
Morning light falls across the sea of clouds and immortal mountains; gold and blue mist flows between the peaks; bells hang from the eaves of the palace on the cliff; a jade terrace is set with a long table of cups and vessels; cranes circle overhead; petals and thin silk drift in the wind. The camera pushes slowly from the foot of the mountain, passes through the rolling clouds into the palace gate, glides past the banquet and corridors, then pulls back and rises, bringing the palace, pines, rocks, birds, and clouds into view layer by layer. The image finally opens into a vast blue-green landscape, with the immortal mountains and sea of clouds faintly visible in the morning light. Overall Chinese xianxia style, 30-second long take, cinematic lighting, fine brushwork detail, volumetric light, flowing clouds and mist, film grain, 1080P, 16:9. No dialogue, no subtitles, no character close-ups.

② Generate the 30-second 1080P video in one pass

# Text-only input (omit --image for text-to-video); --duration 30 is the single-generation limit, --resolution 1080P, --ratio 16:9.
# Replace the scene description with your own subject, but keep the camera timeline and the negative constraints at the end.
# --async returns a task_id first: a 30-second video takes about ten minutes, and the default synchronous wait can hit a client polling timeout.
bl video generate --api-key "$API_KEY" --base-url "$BASE_URL" --model wan3.0-video \
  --prompt "Chinese-style immortal mountain sea of clouds cinematic B-roll long take: at dawn, layered dark green peaks rise from a churning sea of clouds, golden morning light pierces the mist and falls on the summits, a flock of cranes flies low across the cloud waves, ancient pines on the cliff are wrapped in mist and sway gently in the mountain wind; the camera slowly pushes forward from high altitude, passes through the clouds, and reveals an immortal palace pavilion surrounded by white jade balustrades on the highest peak, the lintel is clean with no plaque or inscription, a long banquet table is laid out in front of the pavilion with faintly glowing jade cups, purple-gold cloud energy flows around the seats, petals drift onto the table; then the camera slowly pulls back and rises, the pavilion fades into the peaks, and the sea of clouds, peaks, and rising sun unfold into a vast blue-green landscape vista, the image slowly freezes as light and shadow flow. Overall Eastern xianxia aesthetic, 35 mm film texture, ultra-high detail, volumetric light and Tyndall effect, naturally flowing sea of clouds, epic camera movement, no dialogue, no subtitles, no character close-ups, no recognizable text, calligraphy, inscriptions, signatures, seals, or plaque lettering in the frame, no picture frames, borders, scrolls, or hanging scroll elements." \
  --resolution 1080P --duration 30 --ratio 16:9 --watermark false --async --output json

# Returns {"task_id": "<task ID>"}; poll until SUCCEEDED:
curl -s -H "Authorization: Bearer $API_KEY" "$BASE_URL/api/v1/tasks/<task ID>"

# After SUCCEEDED, download from output.video_url (the link is valid for 24 hours, so save it promptly):
curl -s -L "<output.video_url>" -o xianshan_30s.mp4

Notes

  • Design for one 30-second take: 30 seconds is the single-generation limit of wan3.0-video. Longer videos require multiple generations and stitching, but each generation adds different music and ambient sound; the score and visual style are not guaranteed to match across calls, and the joins can jump in both picture and sound.
  • Constrain "no dialogue" explicitly: If the prompt does not end with "no dialogue, no subtitles, no character close-ups", the model may add voices or subtitles on its own. If you want a voiceover, write the lines into the prompt so the model generates the voice and lip movement natively.
  • Compliance: The immortal mountains, sea of clouds, and palace banquet are fictional scenes generated by the model, with no real people, landmarks, or third-party trademarks. This demo is generated with --watermark false and has no "AI generated" watermark. To keep the mark, omit the flag (the Profile setting applies; the CLI default is true) or pass --watermark true. When publishing AI-generated content, follow the applicable AI content labeling requirements; the watermark is disabled here only for demo asset production.