

A text model writes the title, body, and tags, then text-to-image produces a vertical cover and renders the title text directly into the image.
Disclaimer: All content shown on this page is generated by AI models and is for reference only; it does not constitute any guarantee of results. Actual output and Credits consumption are subject to "Usage Details" in the console.
qwen3.7-plus (title + body + tags) → wan2.7-image (3:4 cover, including title text rendering).
Result
Running the theme "cool summer home decor" through the full pipeline produces this Xiaohongshu cover (with title text rendered):
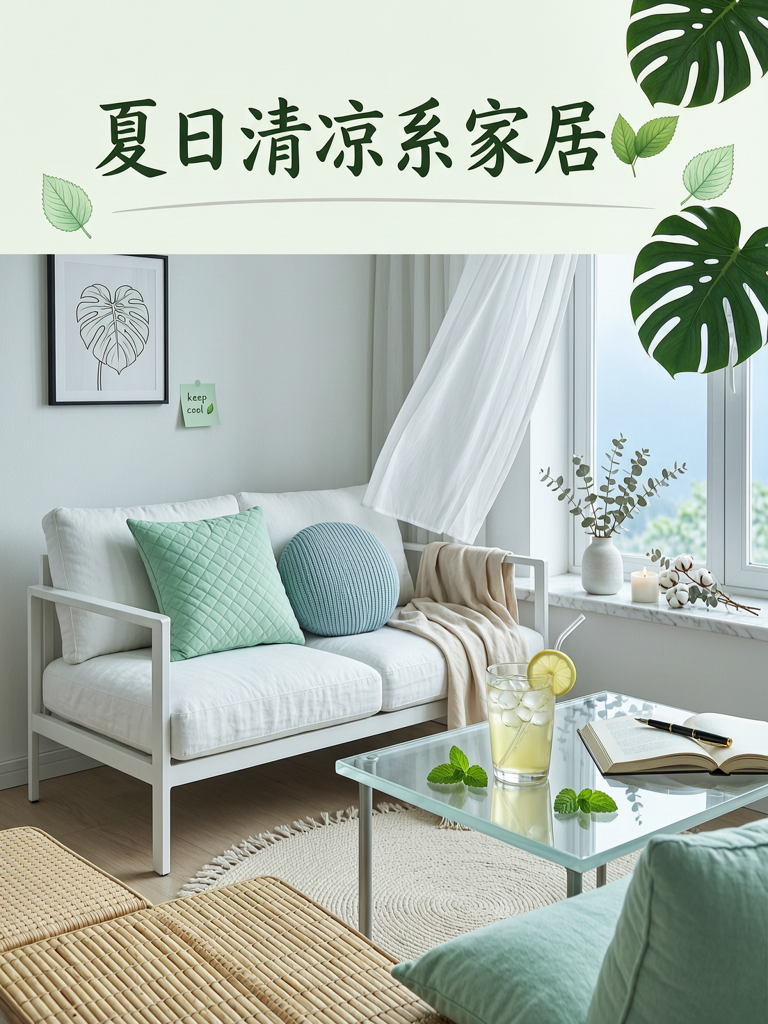
Step 1: Generate viral copy
Send the theme to qwen3.7-plus to produce the title, body, and hashtag tags:
Step 2: Text-to-image to produce the cover
Send the title and visual description to wan2.7-image at size 768*1024 vertical:
View the raw copy output of Step 1 (qwen3.7-plus)
View the raw copy output of Step 1 (qwen3.7-plus)
Notes
- Consumption: This playbook involves copy generation (
qwen3.7-plus) and cover image generation (wan2.7-image, 768*1024 vertical, including title text rendering). - Text rendering: Writing the title into the image prompt lets the cover carry the text directly, skipping post-production typesetting.