

Throughput Reservation (formerly TPM Reservation) locks dedicated inference capacity for a specified model, ensuring that your services are not affected by public rate limits during peak business hours. This topic describes how to create, integrate, and manage Throughput Reservation.
Overview
With a TPM (Tokens Per Minute) reservation, you can lock dedicated inference throughput for a specified model. Calls within the reserved capacity are not subject to the rate limits of the public resource pool.
- Capacity guarantee: The reserved TPM capacity is dedicated to your workload and is not shared with other users.
- Dedicated model code: After you create a Throughput Reservation, the system automatically generates a dedicated model code. You must replace the
modelparameter in your API requests with this code. - Overflow strategy: When creating a reservation, you can choose how to handle excess traffic — automatically overflow to pay-as-you-go (default, no service interruption) or use reserved capacity only (excess requests return 429, no additional charges incurred).
- Add Capacity Package: Purchase additional capacity instances on top of an existing reservation. The new instance shares the same dedicated model code, and the total reserved capacity increases accordingly. See Management operations.
- 8-hour time-slot reservation: In Standard mode, you can opt for pre-paid (by 8-hour time slot), fixed at 8 hours and effective immediately, suitable for scenarios where load is concentrated in specific time slots. For more information, see Throughput Reservation billing.
Compare and select a plan
Model Studio offers multiple capacity and billing plans for inference calls, including pay-as-you-go, resource plans and savings plans, Throughput Reservation, and PTU dedicated deployments. Each plan has different characteristics regarding billing unit, capacity guarantee level, overflow handling, and integration changes. This section helps you choose the appropriate plan based on your business needs.
Plan | Billing unit | Capacity guarantee | Use cases | Overflow handling | Code changes |
|---|---|---|---|---|---|
Pay-as-you-go | Per token | None (shared public pool) | Highly variable/short-term traffic | Served automatically, subject to public rate limits | No changes required |
Resource plan/Savings plan | Prepaid quota | Committed-use discount (not dedicated capacity) | Cost optimization | Excess traffic switches to pay-as-you-go | No changes required |
Throughput Reservation | Prepaid per kTPM | Dedicated capacity with a firm guarantee | Predictable traffic, no tolerance for rate limiting | Optional: auto-overflow to pay-as-you-go (default) / reserved-capacity-only returns 429 | Replace the model parameter |
PTU (Model deployment) | Prepaid per kTPM | Dedicated deployment instance | High throughput and high performance | Optional: auto-overflow to pay-as-you-go (default) / PTU-capacity-only returns 429 | Replace the model parameter |
Supported models
For prices, see Throughput Reservation billing.
- China (Beijing)
- Singapore
- Qwen3.8-Max
- Qwen3.7-Flash-2026-07-15
- Qwen3.7-Max-2026-05-20
- Qwen3.7-Plus-2026-05-26
- Qwen3.6-Flash-2026-04-16
- GLM-5.3
- GLM-5.2
- GLM-5.1
- DeepSeek-v4-Flash
- DeepSeek-v4-Flash-0731
- DeepSeek-v4-Pro
- DeepSeek-v4-Pro-0813
- Kimi-K2.6
Billing and usage notes
- Billing starts once deployment succeeds. Calls within the reserved capacity incur no additional charges. Prepaid fees are paid in a one-off upfront payment and remain in effect from the moment of purchase. Refer to the Bailian console for the actual charges.
- For the billing rules and sales constraints of the 8-hour time-slot reservation (pre-paid by 8-hour time slot), see Throughput Reservation billing.
- When the overflow policy is "Auto overflow": requests exceeding the quota degrade to standard pay-as-you-go billing without service interruption. You can view the degradation count on the detail page at Overflow degradation statistics. When set to "Reserved capacity only": requests exceeding the quota return 429 and incur no additional charges.
- Within 2 hours after the service expires, the instance can still be called and renewed; from 2 to 14 hours after expiry, the instance is stopped, cannot be called, but can still be renewed; after 14 hours, the instance is released and cannot be recovered. (Based on the daily reservation policy; the 8-hour time-slot reservation does not apply to this grace period. For details, see 8-hour time-slot reservation billing.)
Create a Throughput Reservation
Prerequisites: Bailian model service is activated and a workspace has been created. Sign in to the Bailian console and click Create Throughput Reservation.
On the Create Throughput Reservation page, fill in parameters including reservation name, model, billing cycle, input TPM, output TPM, purchase duration, auto-renewal on expiry, and overflow policy. The right side of the page provides a TPM capacity calculator to help with estimation.
-
Fill in the following parameters:
Parameter
Description
Required
Value description
Reservation name
Custom name for identification.
Yes
≤ 50 characters
Select model
Select the model for which to reserve capacity. A dedicated model code is generated automatically upon submission.
Yes
Only models that support Throughput Reservation are available; refer to the console display.
Performance mode
Inference performance tier that determines the output rate of the capacity.
Yes
Standard mode (same TPS as the standard API) / High-speed mode (PTU model deployment, 1.5–2× TPS improvement over the standard API)
Billing cycle
Billing cycle.
Yes
Daily; 8-hour time slot (Standard mode only; fixed 8 hours, effective immediately. For details, see Throughput Reservation billing)
Input TPM
Reserved input throughput, in kTPM (1 kTPM = 1,000 tokens/minute).
Yes
The starting value and step vary by model; refer to the console display.
Output TPM
Reserved output throughput, in kTPM.
Yes
The starting value and step vary by model; refer to the console display.
Purchase duration
Valid duration of the reservation.
Yes
Enter the number of days in the input box. Supported values: 1-30, 60, 90, 120, 365 days.
Auto-renewal on expiry
Automatically deducts payment and renews at 08:00 one day before expiry. Enabled by default. The 8-hour time slot does not support renewal; this parameter does not apply.
No
On / Off
Single renewal duration
Duration of each automatic renewal.
No
Enter the number of days in the input box. The value range is the same as the purchase duration.
Overflow policy
How requests exceeding the reserved capacity are handled when it is exhausted.
Yes
Auto overflow to per-token pay-as-you-go (default; overflow switches to pay-as-you-go, no service interruption) / Reserved capacity only (overflow returns 429, no additional charges)
- After confirming the parameters, click Buy now. In the fee confirmation dialog, verify the charges and click Confirm payment.
- On the Overview tab of the Throughput Reservation detail page, find the Dedicated model code and click copy.
-
Replace the
modelparameter in your API request with the copied dedicated model code:Prerequisite: a Throughput Reservation instance has been created and its status is Running.
Thethinking_budgetparameter of GLM-5.2 (which limits thinking length) does not take effect when called.
TPM capacity calculator
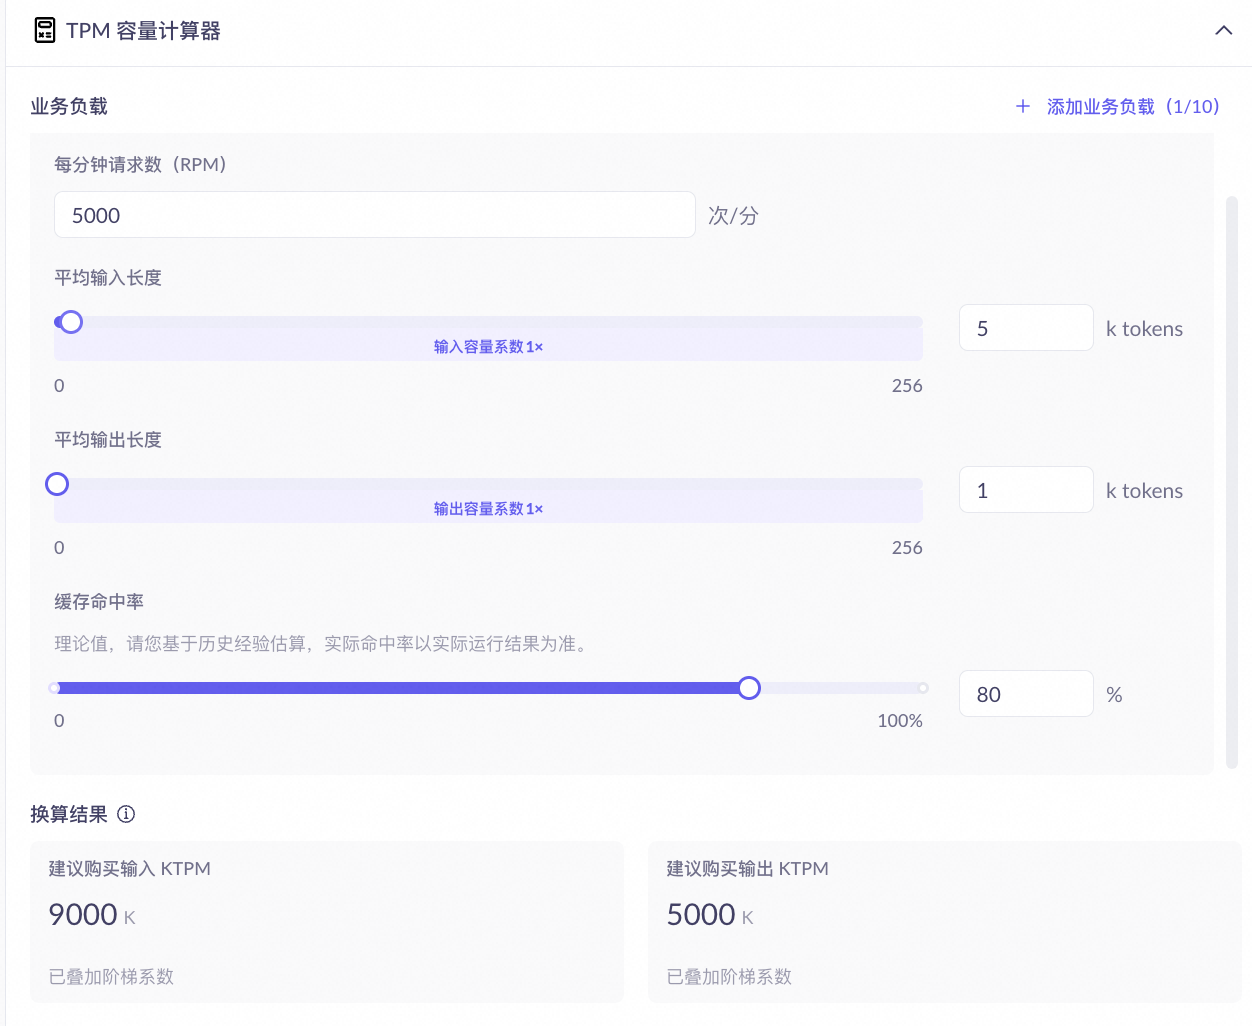
The TPM capacity calculator on the right side of the creation page helps you estimate the TPM quota to purchase based on your business load. After you fill in the following parameters, the calculator automatically outputs the recommended input TPM and output TPM.
Parameter | Description | Impact on result |
|---|---|---|
Requests per minute (RPM) | Number of requests sent per minute during peak business hours. | The larger the RPM, the larger the recommended input and output TPM in proportion. |
Average input length (tokens) | Average number of input tokens per request. | The longer the input, the higher the tier and the larger the coefficient, so the higher the recommended input TPM. Tier boundaries differ by model; refer to the actual console display. |
Average output length (tokens) | Average number of output tokens per request. | The longer the output, the larger the coefficient may be, so the higher the recommended output TPM. |
Cache hit rate | The proportion of requests whose repeated prefixes are cache hits. The actual hit rate depends on the repetition of request content; refer to the runtime result. | The higher the hit rate, the slower the input capacity is consumed, so the lower the recommended input TPM. Affects only input TPM, not output TPM. |
View and manage
Go to the Bailian console and open the reservation list page. The list displays all reservation instances as model cards and supports filtering by model, time, and status.
On the Throughput Reservation page, each model card shows the active reservation count, reserved input/output TPM, and peak utilization ratio. The reservation list table includes columns for reservation ID, input/output TPM, status, billing method (daily, 8-hour time slot, hourly, etc.) and expiry date, and supports filtering by model, time, and status.
Reservation details
Click a target model card to open the detail page, which contains the following 3 tabs:
- Overview
- Monitoring
- API access
- Basic information: reservation name, dedicated model code (copyable), base model, input/output capacity.
- Statistics cards (last 7 days): active reservation count, total and peak TPM usage, average utilization.
- Utilization trend: switch between input/output directions; shows the reserved capacity line and actual usage.
- Overflow degradation statistics: shows the number of requests degraded after exceeding the reserved capacity (degradation occurs only under the "Auto overflow" policy).
Management operations
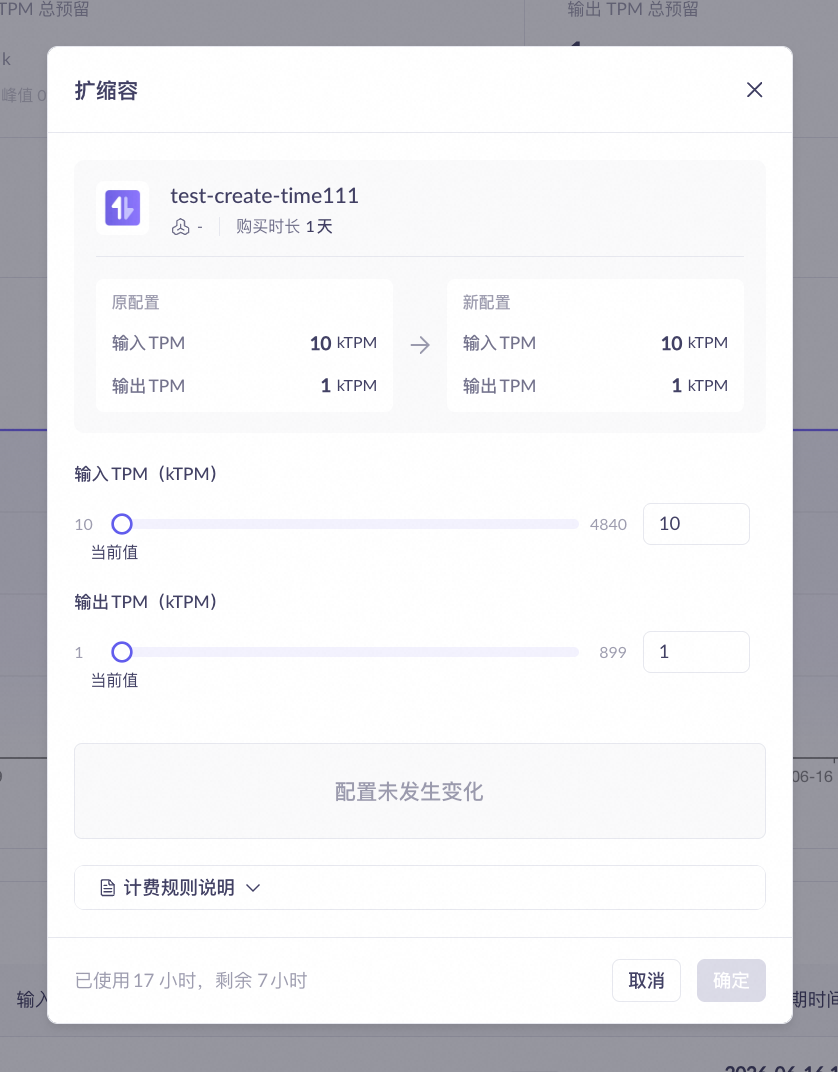
On the target card on the reservation list page or in the detail page, you can perform the following management operations on a reservation instance. 8-hour time-slot reservation instances do not support scaling, renewal, or unsubscription (the capacity automatically becomes invalid after the time slot expires).
- Add Capacity Package
- Scaling
- Renewal
- Unsubscribe
- Dedicated model code, base model, performance mode (Standard/High-speed), and overflow policy: inherited from the base reservation and cannot be changed.
- Existing packages: the number of capacity instances already added.
Parameter | Description | Required | Value description |
|---|---|---|---|
Billing cycle | The billing cycle of the add-capacity package is constrained by the base reservation's billing method: if the base reservation is pre-paid, only pre-paid add-capacity packages can be selected; if the base reservation is post-paid, both pre-paid and post-paid add-capacity packages are available. High-speed mode supports post-paid or pre-paid; Standard mode only supports pre-paid (daily or 8-hour time slot). | Yes | Post-paid/Hourly / Pre-paid/Daily / Pre-paid/8-hour time slot (Standard mode only; capacity increases within the window and becomes invalid outside the window. For rules, see Throughput Reservation billing) |
Input capacity | Added input throughput, in kTPM. | Yes | Starts at 10 kTPM, step 10 kTPM. |
Output capacity | Added output throughput, in kTPM. | Yes | Starts at 1 kTPM, step 1 kTPM. |
Purchase duration | Valid duration of the add-capacity package. Required only for Pre-paid/Daily; Post-paid/Hourly bills by actual duration and needs no entry. | Yes | 1~30, 60, 90, 120, 365 days. |
Auto-renewal on expiry | Applies only to Pre-paid/Daily. Automatically deducts payment and renews at 08:00 one day before expiry. | No | On / Off |
Reservation instance status
Reservation instance status
Status | Description |
|---|---|
Running | Running normally; can be called using the dedicated model code. |
Pending | Created; waiting to take effect. |
Modifying | Scaling in progress; service is not interrupted during this period. |
Stopped | Stopped due to reasons such as overdue payment; can be restored after renewal. |
Released | Reservation ended without renewal or via unsubscription; resources have been released and are irreversible. |
FAQ
Q: What happens when the reserved capacity is exceeded?
Q: What happens when the reserved capacity is exceeded?
Q: How do I obtain the dedicated model code?
Q: How do I obtain the dedicated model code?
model parameter in your API request with this code to use the reserved capacity.Q: What happens when a reservation expires?
Q: What happens when a reservation expires?
Q: How do I determine whether to scale up?
Q: How do I determine whether to scale up?